


trust mode
Privacy by default to build confidently
Privacy and verification options available whether you call the models through one API, build in your browser without writing code, or download the weights and run them yourself.
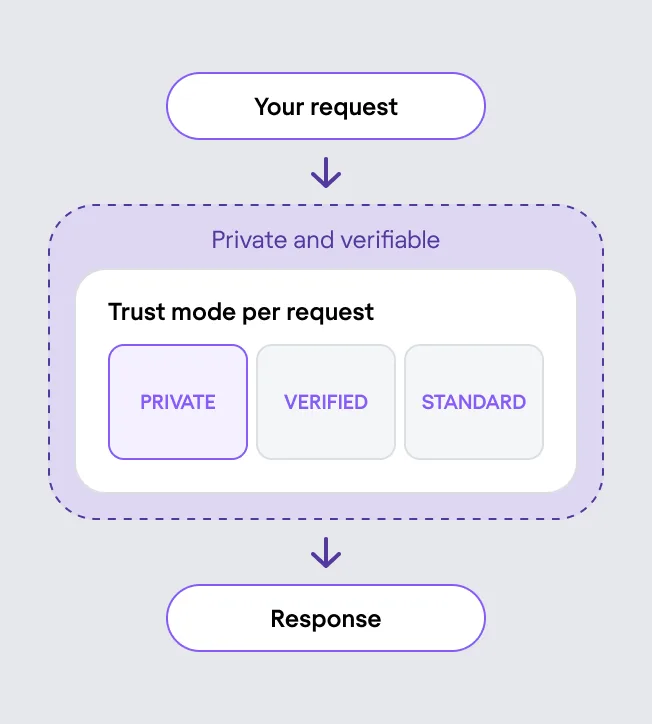
Trust per request
0G Private API

One endpoint for the whole model catalogue, with a trust mode you set per call: sealed enclave, attested routing, or straight through. Nothing retained, on any plan.
Best for matching protection to the task.
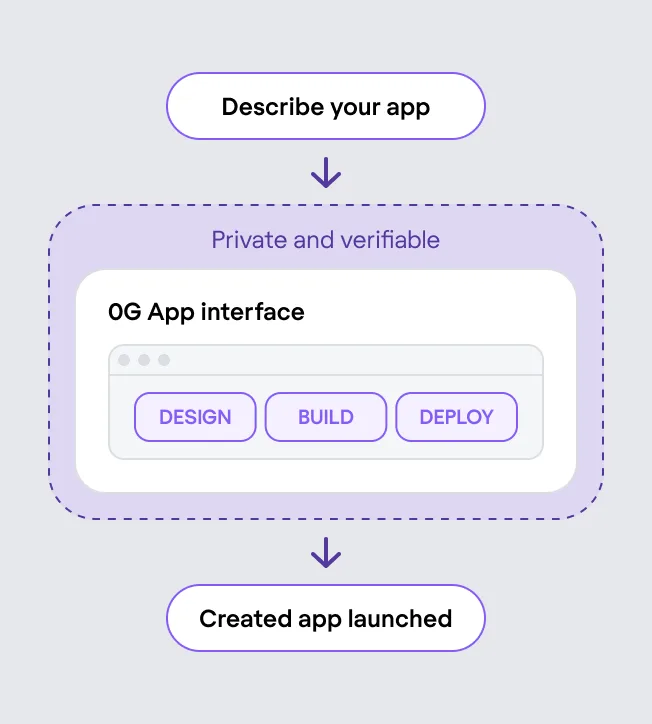
No code, same guarantees
0G App
Describe an app and launch it from the browser. The inference underneath runs in the same sealed enclaves as the API, so what you build inherits the privacy instead of trading it away.
Best for shipping apps without a codebase.
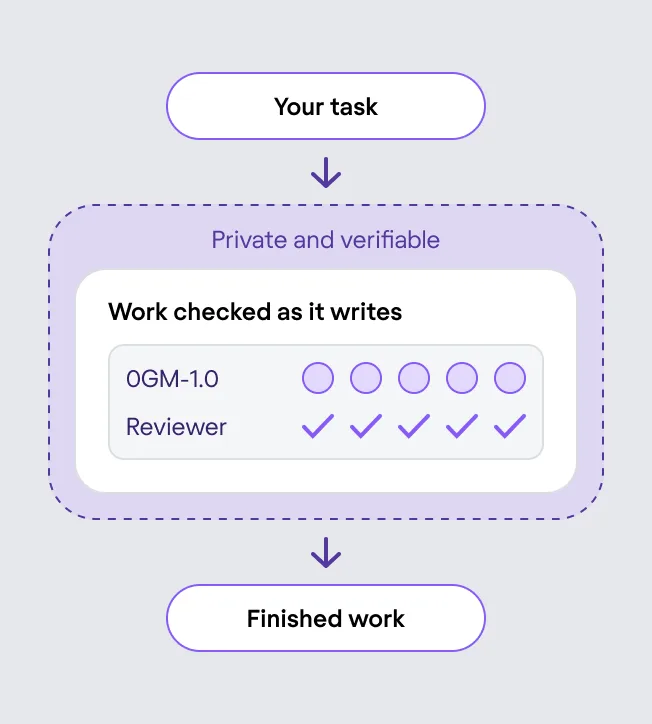
Models we built
0GM Models
They do the work rather than describe how to do it. Quality holds from the first step to the last, because a separate model reviews each one as it's written. It costs a fraction of frontier models.
Best for getting it right first time.
Trust modes
Not every task needs the same privacy.

Private, enclave sealed
9 models
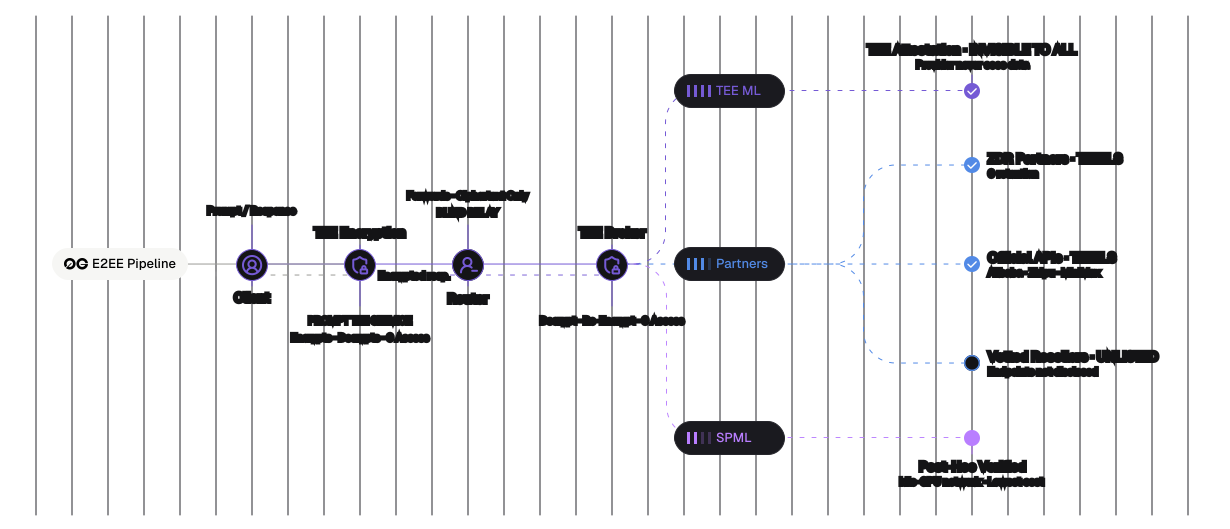
The prompt is encrypted end-to-end and opens only in hardware. Zero data retention, while staying cryptographically verifiable. No one can see your data, not even us.
Best for sensitive data
 0GM-1.0-35B-A3B
- 0GM-1.0-35B-A3B-SIA
 Whisper Large v3
 Qwen3 Embedding 8B
 GLM-5.3
 Laya
 Vela 2.0 9B
 Z-Image-Turbo

Verified, route attested
66 models
Every single request carries proof of which model answered. Published onchain and checkable against the hardware vendor's root of trust.
Best for apps that need provenance
- Qwen3.7 Embedding
- 0GM-1.0-35B-A3B
- 0GM-1.0-35B-A3B-SIA
- Qwen3 Embedding 8B
- GLM-5.3
- Laya
- Vela 2.0 9B
- Whisper Large v3

Standard routing
52 models
The frontier models you already build with, reachable through the same API and the same billing as everything else on 0G. Best price and availability across the full catalog.
Best for everyday tasks
 MiniMax-M3.1-Flash
 DeepSeek-V4.1-Flash
- Qwen3.8-Max
- GLM-5.3-Flash
 Claude Opus 5.5
- GPT-6.1 Sol
 Gemini 3.6 Flash
 Kimi-K3
- 38M+Requests served
- 667BTokens processed
- 138Models
- 0Bytes of data retained
Everything for your security team
Answered and published, including the parts we're still building.
Your data
- Nothing keptPrompts and responses are not stored, by default and by contract, on every plan.
- Sealed processingInference runs inside hardware enclaves. 0G and cloud operators cannot read it.
- Where it runsInference runs on bare metal in Japan. Account data and logs held in the USA.
UPCOMING
- Region pinningKeep compute and storage in a chosen country.
- Retention windowsSet how long files, chat history and agent memory are kept.
- Verifiable deletionA deletion record you can check, for GDPR and CCPA requests.
AI safety
- Guardrails before the model runsRules on data, models, spend and outputs block or hold a request before it reaches the model.
- Private models onlyOne switch keeps the whole organization on models that run in sealed compute.
- Human reviewOutputs that leave the company wait for an approver.
UPCOMING
- Agent controlsEach agent gets its own tools, data access and budget, and a kill switch.
- Security testingAutomated attack scans on every agent, with fixes applied as guardrails.
- Risk classificationAgents mapped to EU AI Act tiers automatically.
Proof
- Receipt on every requestA hardware-signed record of which enclave served your request, and that nothing was kept.
- Verify it yourselfRun one command against our gateway and check it against Intel's signature, without trusting 0G.
- Security documentationArchitecture, data flows and the trust model are published.
UPCOMING
- Audit log and evidence packsEvery request, agent step and policy change, exported as a signed pack an auditor checks offline.
- SOC 2 Type II and ISO 27001In progress.
- BAAUnder review for healthcare customers.
Encrypted requests
Get answers or start building today
Learn more about enterprise and we'll help you find the right fit. An API key gets you running in minutes.